DeepSeek Open-Sources DeepInfer, the Engine Behind Its Own Chat Traffic
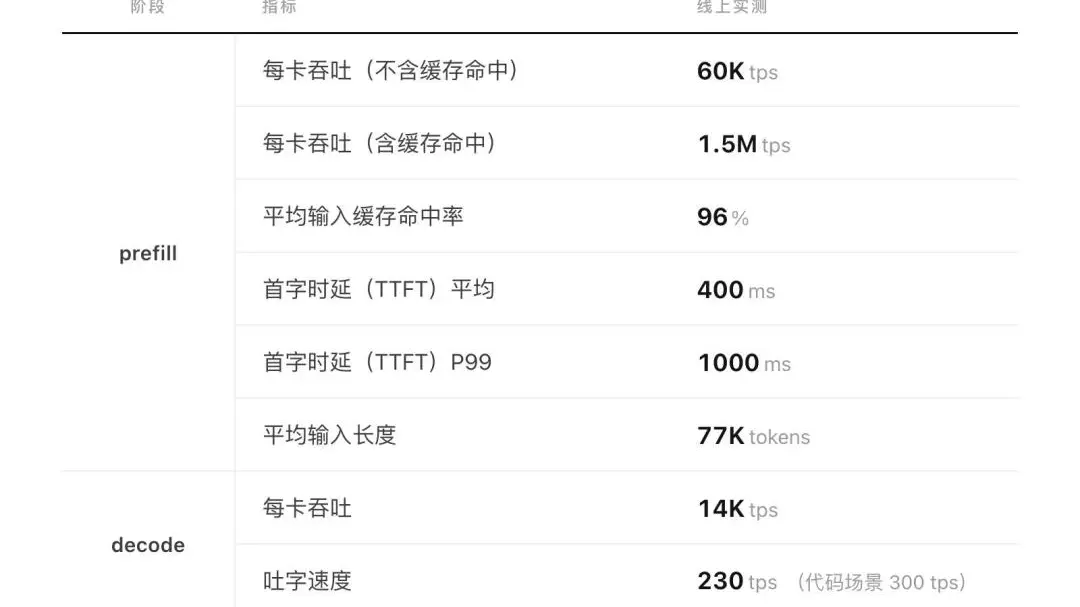
DeepSeek published DeepInfer, the in-house inference framework that powers its production-scale model serving, under the permissive Apache 2.0 license on October 20, together with deepseek-recipe, a companion token encoding and decoding component. The release currently supports DeepSeek-V4.1-Flash.
The framework bundles high-performance operators and an optimization engine, and adds distributed inference, speculative decoding, structured output and a memory-saving technique the company calls SWA Bounded Replay. It runs on both Nvidia hardware and Huawei’s Ascend chips, a detail that matters for Chinese developers who cannot rely on imported GPUs.
DeepInfer follows a pattern for DeepSeek: it has already opened its model weights, its TileLang compiler tooling and its inference operator library. Publishing the serving layer lets outside engineers reproduce the company’s efficiency gains instead of reverse-engineering them, and gives smaller teams a ready-made path to running large models cheaply.
The move also quietly raises the bar for rivals. Inference cost, not raw model quality, increasingly decides which AI products survive at scale, and DeepSeek is handing its cost advantage to anyone who wants it.