Google Researchers Find a Rounding Bug That Quietly Breaks AI Training
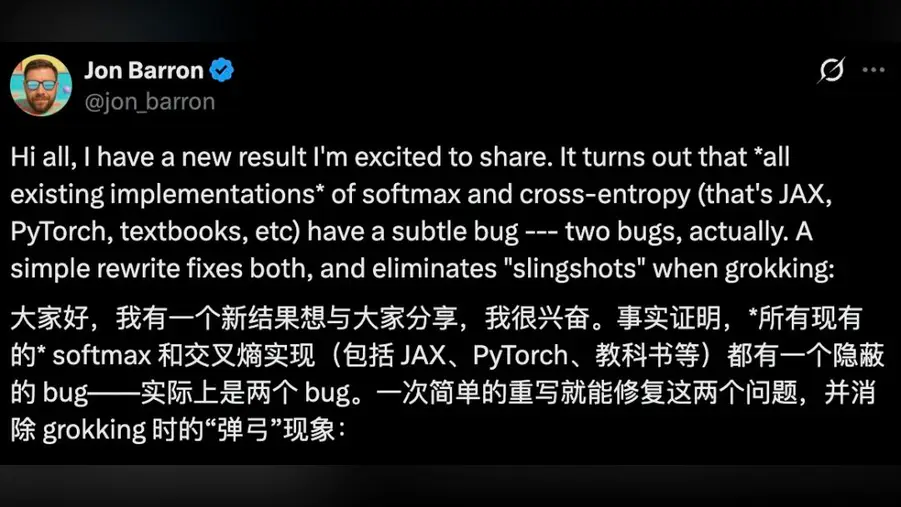
A senior research scientist at Google DeepMind, Jon Barron, has flagged what amounts to a typo with consequences: in the standard implementations of a widely used training algorithm, a number that should carry information is being quietly rounded down to zero. The bug shows up in PyTorch and JAX, two of the most common software frameworks for building AI models, and in the formula printed in textbooks.
The effect is not a crash. It is a slow leak. The more confident a model becomes about a prediction, the more likely the correct training signal is to vanish into that rounding step. With the corrective signal gone, the optimizer that adjusts the model’s weights loses its footing, and the training curve swings instead of settling. In plain terms, the model’s certainty can erase the very feedback meant to correct it.
Why this matters beyond a research seminar is scale. PyTorch and JAX underpin most of the large language models and image generators in commercial use, from American labs to Chinese developers such as DeepSeek and Alibaba’s Qwen team, which publish open models built on the same toolchain. A subtle arithmetic flaw in a shared library is one of the few things that can touch competitors on both sides of the Pacific at once.
According to the account, Google’s Gemini model was able to identify and then correct the problem in its own training setup, an early demonstration of a model auditing the code that builds models. That detail is likely to draw as much attention as the bug itself, because it suggests automated review of training pipelines could become routine rather than a novelty.
The practical questions are unglamorous but large. How much of the gap between a well-behaved training run and a jittery one was this rounding step? Were some models written off as hard to train when the fault lay in a library default? And how many published benchmark comparisons, including those used to rank Chinese and American models against each other, rest on training runs that carried the flaw?
For teams outside the big labs, the immediate lesson is verification. Framework defaults are treated as ground truth by most engineers, and textbook formulas even more so. A single mis-specified constant can propagate through fine-tuning, distillation and evaluation without anyone noticing, because the output still looks like a model that works, just a less stable one.
The wider point is about where progress in AI now comes from. Much of the recent leap has been credited to bigger clusters and more data. This episode is a reminder that the numerical plumbing underneath, the parts nobody demos, still shapes what models can learn. Fixing a rounding rule will not make headlines the way a new model release does, but it may change training curves for everyone who adopts the correction.